Beyond
the
Helix
Vareom delivers an automated Next Generation Sequencing pipeline with real-time annotation, interactive variant filtering, and comprehensive genomic insights.
Three dedicated branches for every genomic workload.
To support the diverse needs of the scientific and genomic communities globally, we deliver our bioinformatics solutions through three dedicated branches:
Vareom SaaS
RUOOur scalable software-as-a-service model provides research facilities and genomic teams with direct access to the Vareom Platform. It completely automates the NGS data analysis pipeline, allowing teams to manage their workflows internally with maximum speed, privacy, and accuracy.
Vareom Research
RUOWe act as an extended bioinformatics partner for independent researchers and research centers. Using our platform, we help design, execute, and interpret complex genomic investigations to accelerate scientific discoveries.
Vareom Academy
RUOTechnology is only as powerful as the people using it. Our educational division provides hands-on, online training for genomic teams and researchers. Whether you want to master standard bioinformatics workflows or require a customized curriculum tailored to your team’s specific scientific goals, our experts are here to upskill your workforce.
A pipeline that runs itself,
and results you can trust.
Automated end-to-end pipelines
From FASTQ ingestion to annotated VCF, exon CNV analysis, and comprehensive analytical reports — no manual scripting required.
Built-in variant classification
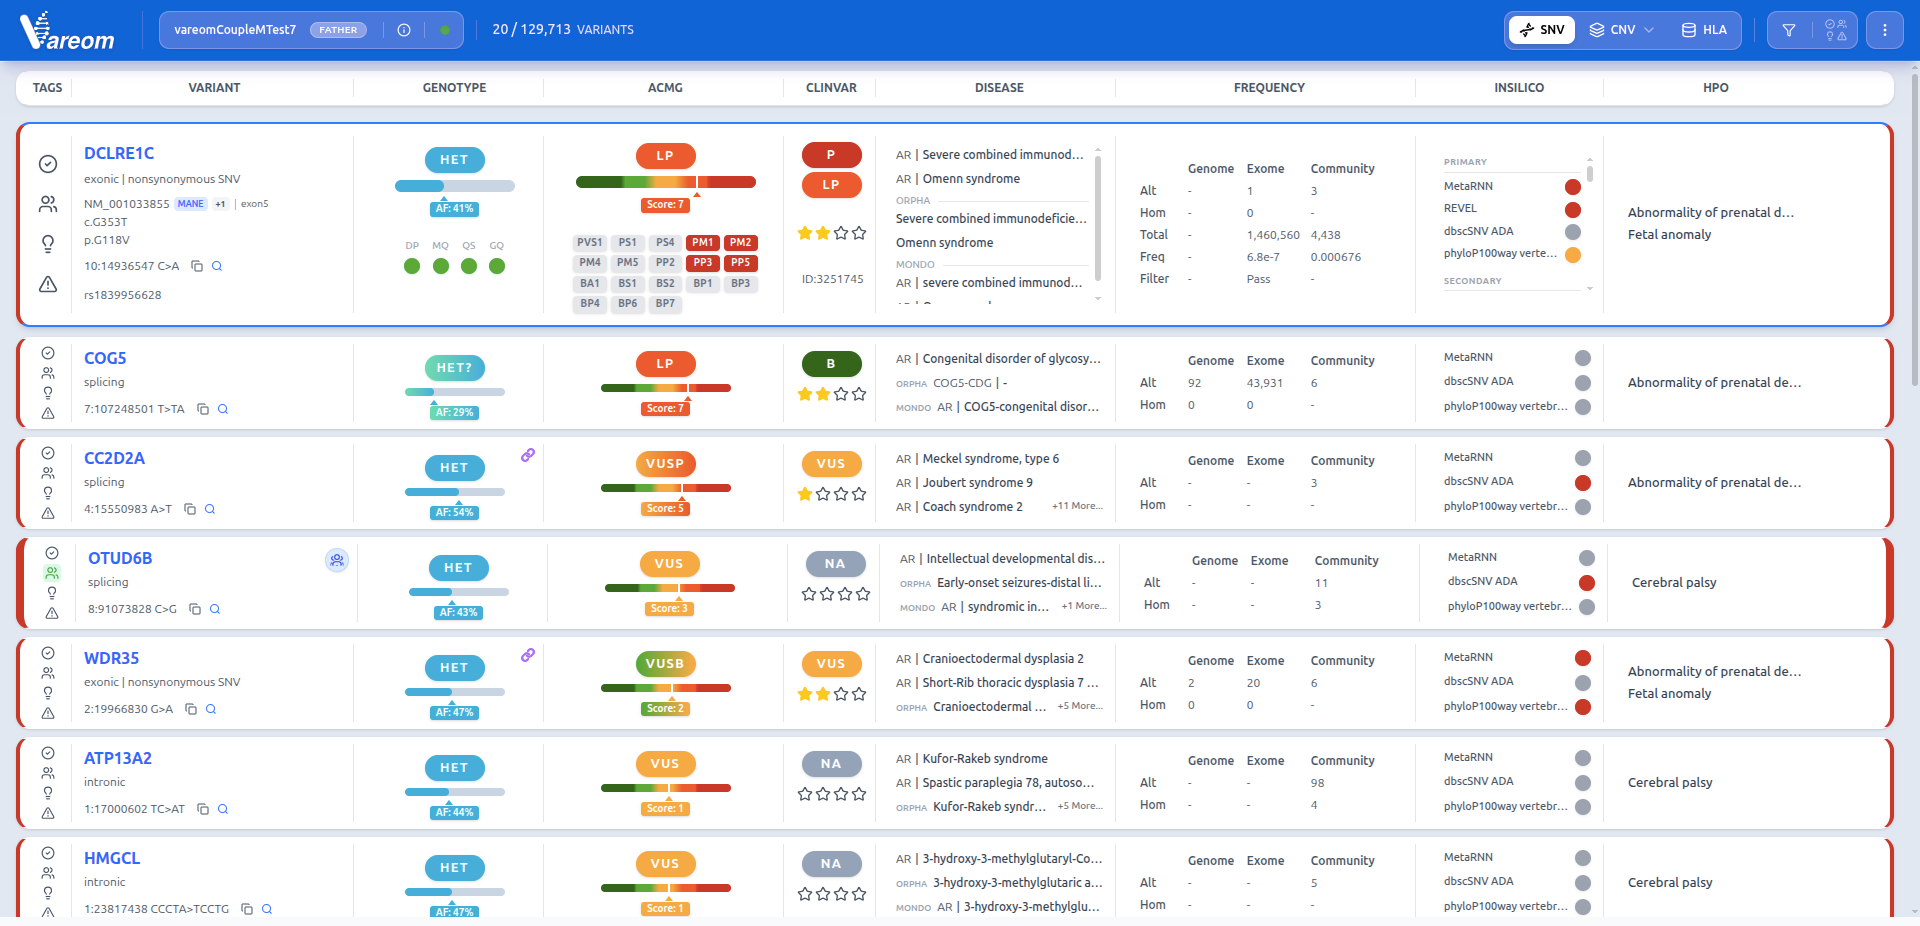
Every call is tagged Pathogenic through Benign using automated ACMG/AMP classification frameworks, shown as clear status badges — never buried in a raw VCF column.
In-browser high-speed analytics
Blazing-fast in-memory variant querying, custom filtering, and dynamic table sorting with zero server latency or data reloading.
Fully reproducible and auditable
Pipeline version, reference genome, and tool versions are pinned and logged. Re-run any analysis from any point in time.
Interactive genomic visualizers
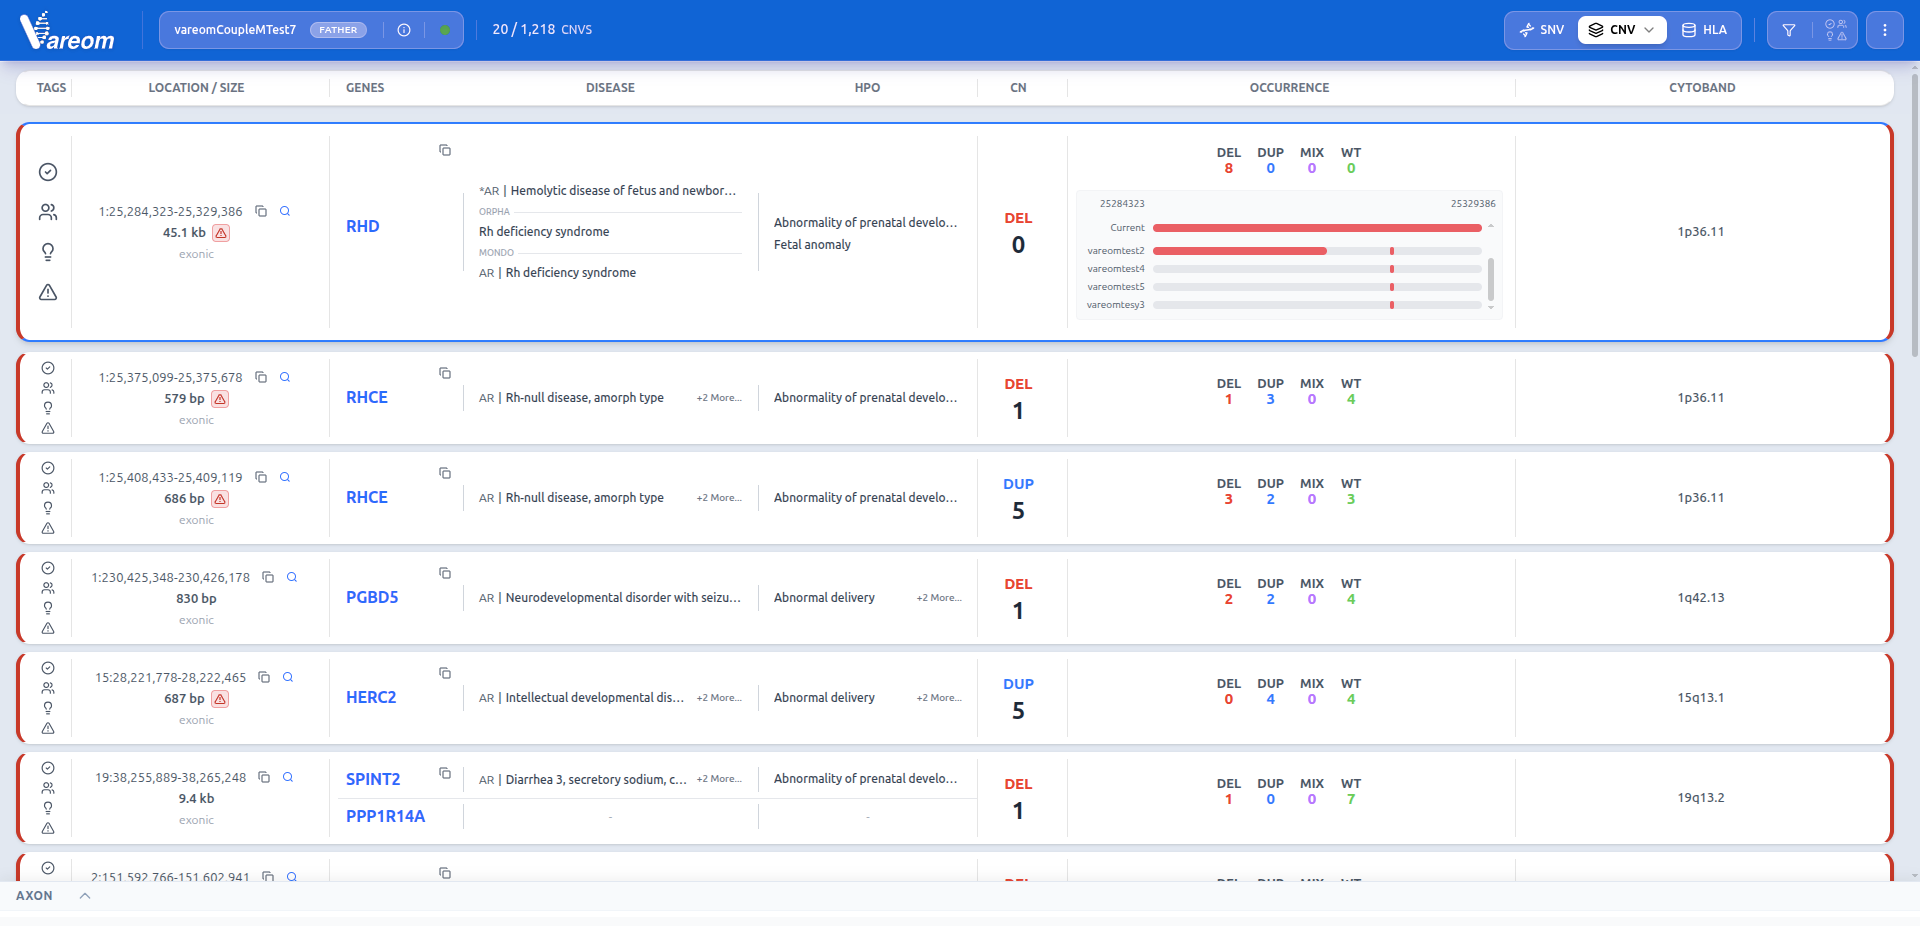
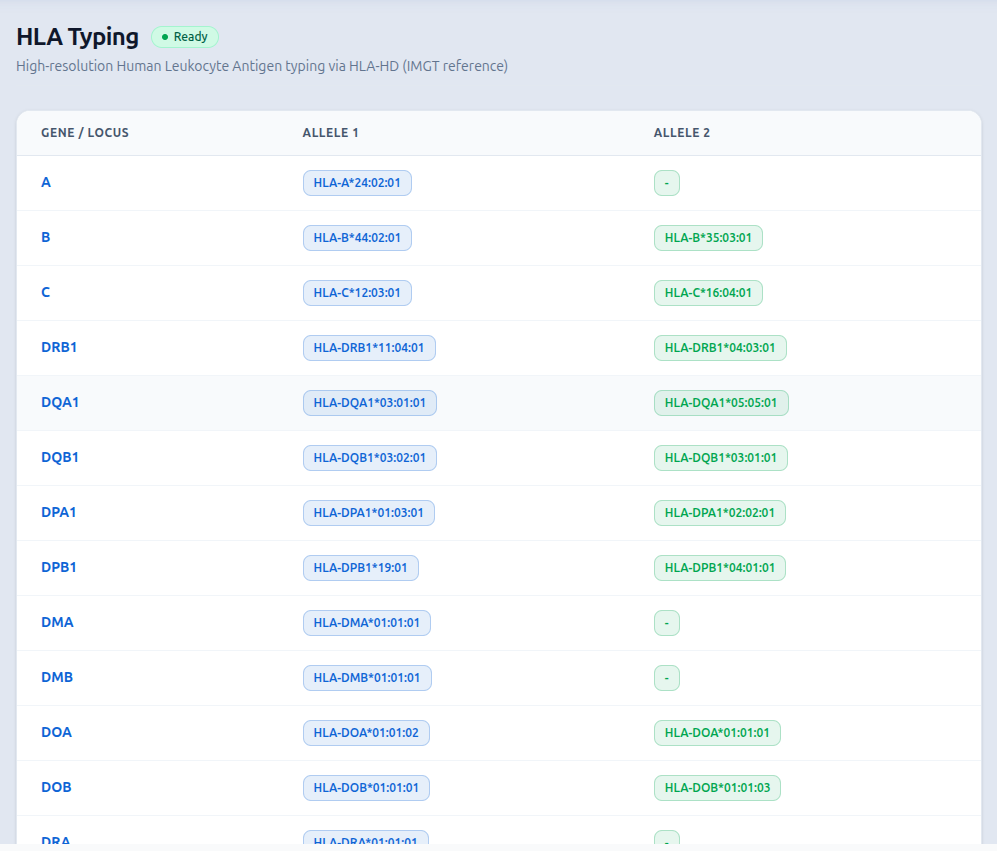
High-resolution HLA typing, dynamic CNV graphs, and in-browser variant analysis built directly into the platform interface.
Data sovereignty and privacy
Institutional control over your genomic datasets with isolated environment options, dedicated security controls, and zero unauthorized data egress.
Four steps from sample to answer.
Read QC and Alignment
Sequence MappingRaw FASTQ reads are aligned to standard reference genomes with optimized speed and coverage sensitivity.
Variant Calling
SNV and InDel DetectionHigh-confidence detection of single nucleotide variants, small insertions, deletions, and exon events.
Variant Annotation
Database IntegrationAutomated annotation with population frequencies, functional consequences, and clinical classifications.
Report Delivery
Diagnostic SummaryStructured analytical summaries and downstream-ready files generated automatically for interpretation.
Every variant, classified and explained.
Your team sees clear pathogenicity badges, exon-level copy ratio graphs, high-resolution HLA typing, and evidence-based assertions — all in one integrated view.
Engineered exclusively for cloud performance.
We manage, scale, and optimize the entire bioinformatics stack on dedicated cloud compute — eliminating infrastructure overhead while maximizing processing speed and analytical accuracy.
Dedicated Cloud Compute
Pre-provisioned, GPU-accelerated cloud nodes configured specifically for WES read alignment and variant calling algorithms.
Elastic Turnaround
Process single samples in under 35 minutes or scale out automatically to process hundreds of cohort exomes concurrently.
Continuous Database Sync
Always up to date with the latest ClinVar, gnomAD, and reference annotation releases without manual database maintenance.
Bridging the gap between raw genomic data and actionable scientific insights.
Our Story
Founded in Erbil
Vareom was founded in Erbil by a dedicated team of bioinformaticians and software engineers. While working within advanced genomic facilities, we witnessed a recurring bottleneck: institutions possessed highly advanced DNA sequencers, but lacked the accessible software infrastructure needed to analyze the massive amounts of genomic data they produced.
Kurdistan Region & Iraq
Initially, Vareom was designed specifically to solve this critical bioinformatics gap within the Kurdistan Region and Iraq. Our goal was to empower local genomic teams to process their data locally, eliminating the need for expensive foreign outsourcing and complex manual coding.
Worldwide Reach
As we built our secure, cloud-based infrastructure, we realized this bottleneck is a global challenge. Today, we have expanded our reach. Through our automated SaaS and online services, Vareom now provides world-class bioinformatics solutions to research centers, independent researchers, and genomic teams anywhere in the world.
Our Mission & The Vareom Platform
Democratizing NGS Insights
Vareom is a comprehensive bioinformatics solutions company dedicated to bridging the gap between raw genomic data and actionable scientific insights.
We believe that brilliant scientific research should not be hindered by a lack of IT expertise. Our mission is to eliminate bioinformatics barriers so clinical researchers, diagnostic laboratories, and genomic institutions can translate raw sequences into life-changing discoveries without computational friction.
Zero-Coding NGS Infrastructure
Our flagship product is the Vareom Platform—a proprietary, cloud-based infrastructure uniquely specialized for Next-Generation Sequencing (NGS) data analysis.
We designed the Vareom Platform with a complete zero-coding interface, empowering research centers, independent investigators, and genomic teams to seamlessly process, manage, and interpret massive datasets without requiring any internal software engineering background.
Partner with Us
Whether you are scaling a local genomic team's capabilities, conducting groundbreaking investigations, or looking to train the next generation of genomic specialists, Vareom provides the robust infrastructure and expert guidance to help you succeed.
News and Updates
Track platform enhancements, pipeline releases, and technical milestones across Vareom services.
Platform v1.3.0: Multi-Sample Family and Cohort Interpretation
Structured family trio analysis for clinical interpretation, automated inheritance pattern classification, and joint variant review.
Platform v1.2.0: High-Resolution HLA Typing & Reporting
Integrated high-resolution HLA allele resolution across Class I and Class II loci with automated quality checks and consolidated reporting.
Platform v1.1.0: Interactive CNV Exploration & Cohort Baselines
Exon-level copy number variant visualization, baseline cohort calibration, and real-time clinical annotation cross-referencing.
Accelerate your NGS pipeline today.
Join leading research facilities and independent genomic teams who trust Vareom for automated, reproducible Next Generation Sequencing data analysis